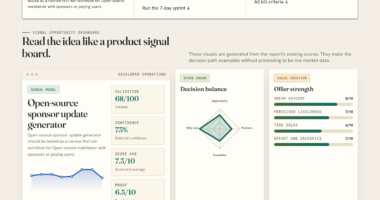
🔍 Read the full analysis: How To Give AI Agents More Room To Make Decisions on ThorstenMeyerAI.com

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Anthropic reported that, by August 2026, employee-directed agents logged six times as many hours as their human directors, while spending about 80% of session time waiting for people. The report argues that human attention—not agent capacity—can become the bottleneck, and offers rules for limiting reviews, experiments, recurring tasks and escalations.
A report published by ThorstenMeyerAI.com on October 27 argues that people using AI agents should set limits on what agents send back and when they ask for help, after an Anthropic study of its own workforce found agents spent about 80% of session time waiting for human input. The report proposes four rules to reduce routine interruptions and reserve human attention for decisions that need it.
According to the account of Anthropic’s study, employee-directed agents logged six times as many hours as their human directors by August 2026. The study estimated that even non-technical employees would need about half their working time to read all the output their agents produced. Those figures describe Anthropic’s workplace, not a representative measurement of all organizations.
The report says the share of sessions spent on “meta-work,” mostly managing agents, rose from 10% in fall 2025 to 22% in spring 2026. It also says written standing instructions for agents grew from a few hundred to 8,500 over a year. The account characterizes the study’s central finding as a shift in the bottleneck: generating more agent output is of limited use if people cannot review and act on it.
Thorsten Meyer’s four proposed rules are to count the human work an agent creates, run small experiments without turning every promising result into a permanent project, set end conditions for recurring tasks, and give coordinating agents an attention budget. Under the last rule, the default should be silence, with no more than three decisions a day presented, each with a recommendation, supporting evidence and the consequence of taking no action.
The new bottleneck
Agents don't get tired. Your attention does.
Anthropic measured how its own staff work with AI agents. The agents now do far more hours. The limit is the person who has to read, check and decide.
An agent drafts the report, the code or the summary in minutes.
- Reading
- Checking
- Deciding
- Fixing
- Explaining it to others
Illustration of the idea, not a measurement.
“An army of Claudes, with every one asking for my attention.”An Anthropic engineer, quoted in the study
Source: Anthropic Economics team, How employment is changing at Anthropic, 16 October 2026. Employee-directed interactive sessions; human time counted as 40 hours a week per head. One company studying its own staff, who chose to adopt the tools.
Powered by Thorsten Meyer AI
Keeping Agent Output Within Human Capacity
The report’s practical concern is that cheap generation does not mean cheap follow-up. An agent can produce a proposal, report or alert quickly, but a person still may need to read it, check its accuracy, decide what to do and take responsibility for the outcome. If those steps are not counted, adding agents can increase the volume of work rather than reduce it.
That issue matters to teams adopting agents for routine research, drafting or monitoring. A stream of individually reasonable updates can compete for attention, while agents waiting for approvals may not complete their tasks any faster. Setting a threshold for interruption and a clear end point for repeated work gives people a way to delegate without treating every output as something that must be reviewed immediately.
The proposed rules are operating suggestions, not measured guarantees. The supplied material does not report a controlled test showing that these four practices improve productivity. Their value will depend on the task, the consequences of errors and the time required for human review.
Products Worth Considering

Ledger Flex Crypto Wallet

Apple MacBook Pro 14 (2021) with M1 Max, 64 GB RAM, 2 TB SSD, Silver

Ledger Flex + Folio Crypto Hardware Wallet
As an affiliate, we earn on qualifying purchases.
What Anthropic’s Workplace Study Measured
The numbers cited in the report come from Anthropic’s own employees, who chose to adopt the tools. The study’s authors, as described by Meyer, cautioned that the company’s work and adoption patterns may not transfer to other workplaces. The findings should be read as evidence of a possible management challenge, not as a universal rate for agent use.
The article also uses examples from Anthropic customer stories to illustrate how people can review consequential outputs. Private chef business owner Dan Ninerell said he used Claude to draft catering proposals and reported earning $20,000 in a month and a half using those proposals; that is his account, published by the vendor. Painting contractor Tony Severino described catching an early blueprint-reading error in which Claude used a floor-area multiplier instead of wall measurements. He now asks the system to “show me your work.” These examples are anecdotes, not independent evaluations of performance.
““I made $20,000 in the last month and a half using Claude to do these professional proposals.””
— Anthropic customer Dan Ninerell, as quoted by Anthropic
Limits of the Evidence and Advice
The source material does not provide the full study methods, sample size or detailed definitions behind every metric. It also does not establish whether Anthropic’s figures apply to other companies, occupations or agent systems. The reported 80% waiting time is an observation about sessions in the studied setting, not proof that agents generally spend that share of time idle.
It is also unclear how much the four rules would change workload or results in practice. The supplied article develops its recommendations but does not provide a measured before-and-after comparison. The customer examples are attributed personal accounts published by Anthropic, rather than independently verified outcome studies.
Testing Rules in Daily Agent Work
The report offers six prompts alongside its four rules, but the supplied material does not include their full wording. Readers applying the approach can start by identifying who must review an agent’s output, what action it may trigger and when a recurring task should stop. Any escalation limit should also reflect the cost of a missed alert and the risk of an incorrect answer.
The next meaningful evidence would be workplace testing that tracks review time, interruptions, errors and completed work before and after teams change their agent instructions. Until such results are available, the recommendations remain a framework to try and evaluate—not a demonstrated productivity formula.
Key Questions
What did Anthropic’s study report about agent activity?
As reported by Thorsten Meyer, employee-directed agents at Anthropic logged six times the hours of the employees directing them by August 2026. The study also found they spent about 80% of session time waiting for human input. These findings come from Anthropic’s own workforce.
What is an attention budget for an AI agent?
It is a limit on how often a coordinating agent interrupts a person. Meyer proposes that the agent default to silence and present at most three decisions per day, each with a recommendation, evidence and the outcome of doing nothing.
Does the study prove that more AI agents increase workload?
No. The figures describe one company and do not establish a general effect across workplaces. The report argues that reviewing agent output can create additional work, but the supplied material does not include a controlled test of the four proposed rules.
How can a person check an agent’s work?
The article describes contractor Tony Severino asking Claude to “show me your work” after catching an error in a blueprint estimate. For consequential tasks, people can ask for supporting steps and check the parts where mistakes would matter most.
Source: ThorstenMeyerAI.com